Nishtha
Soni.
I — building software that solves real problems, from full-stack apps to AI-powered systems.
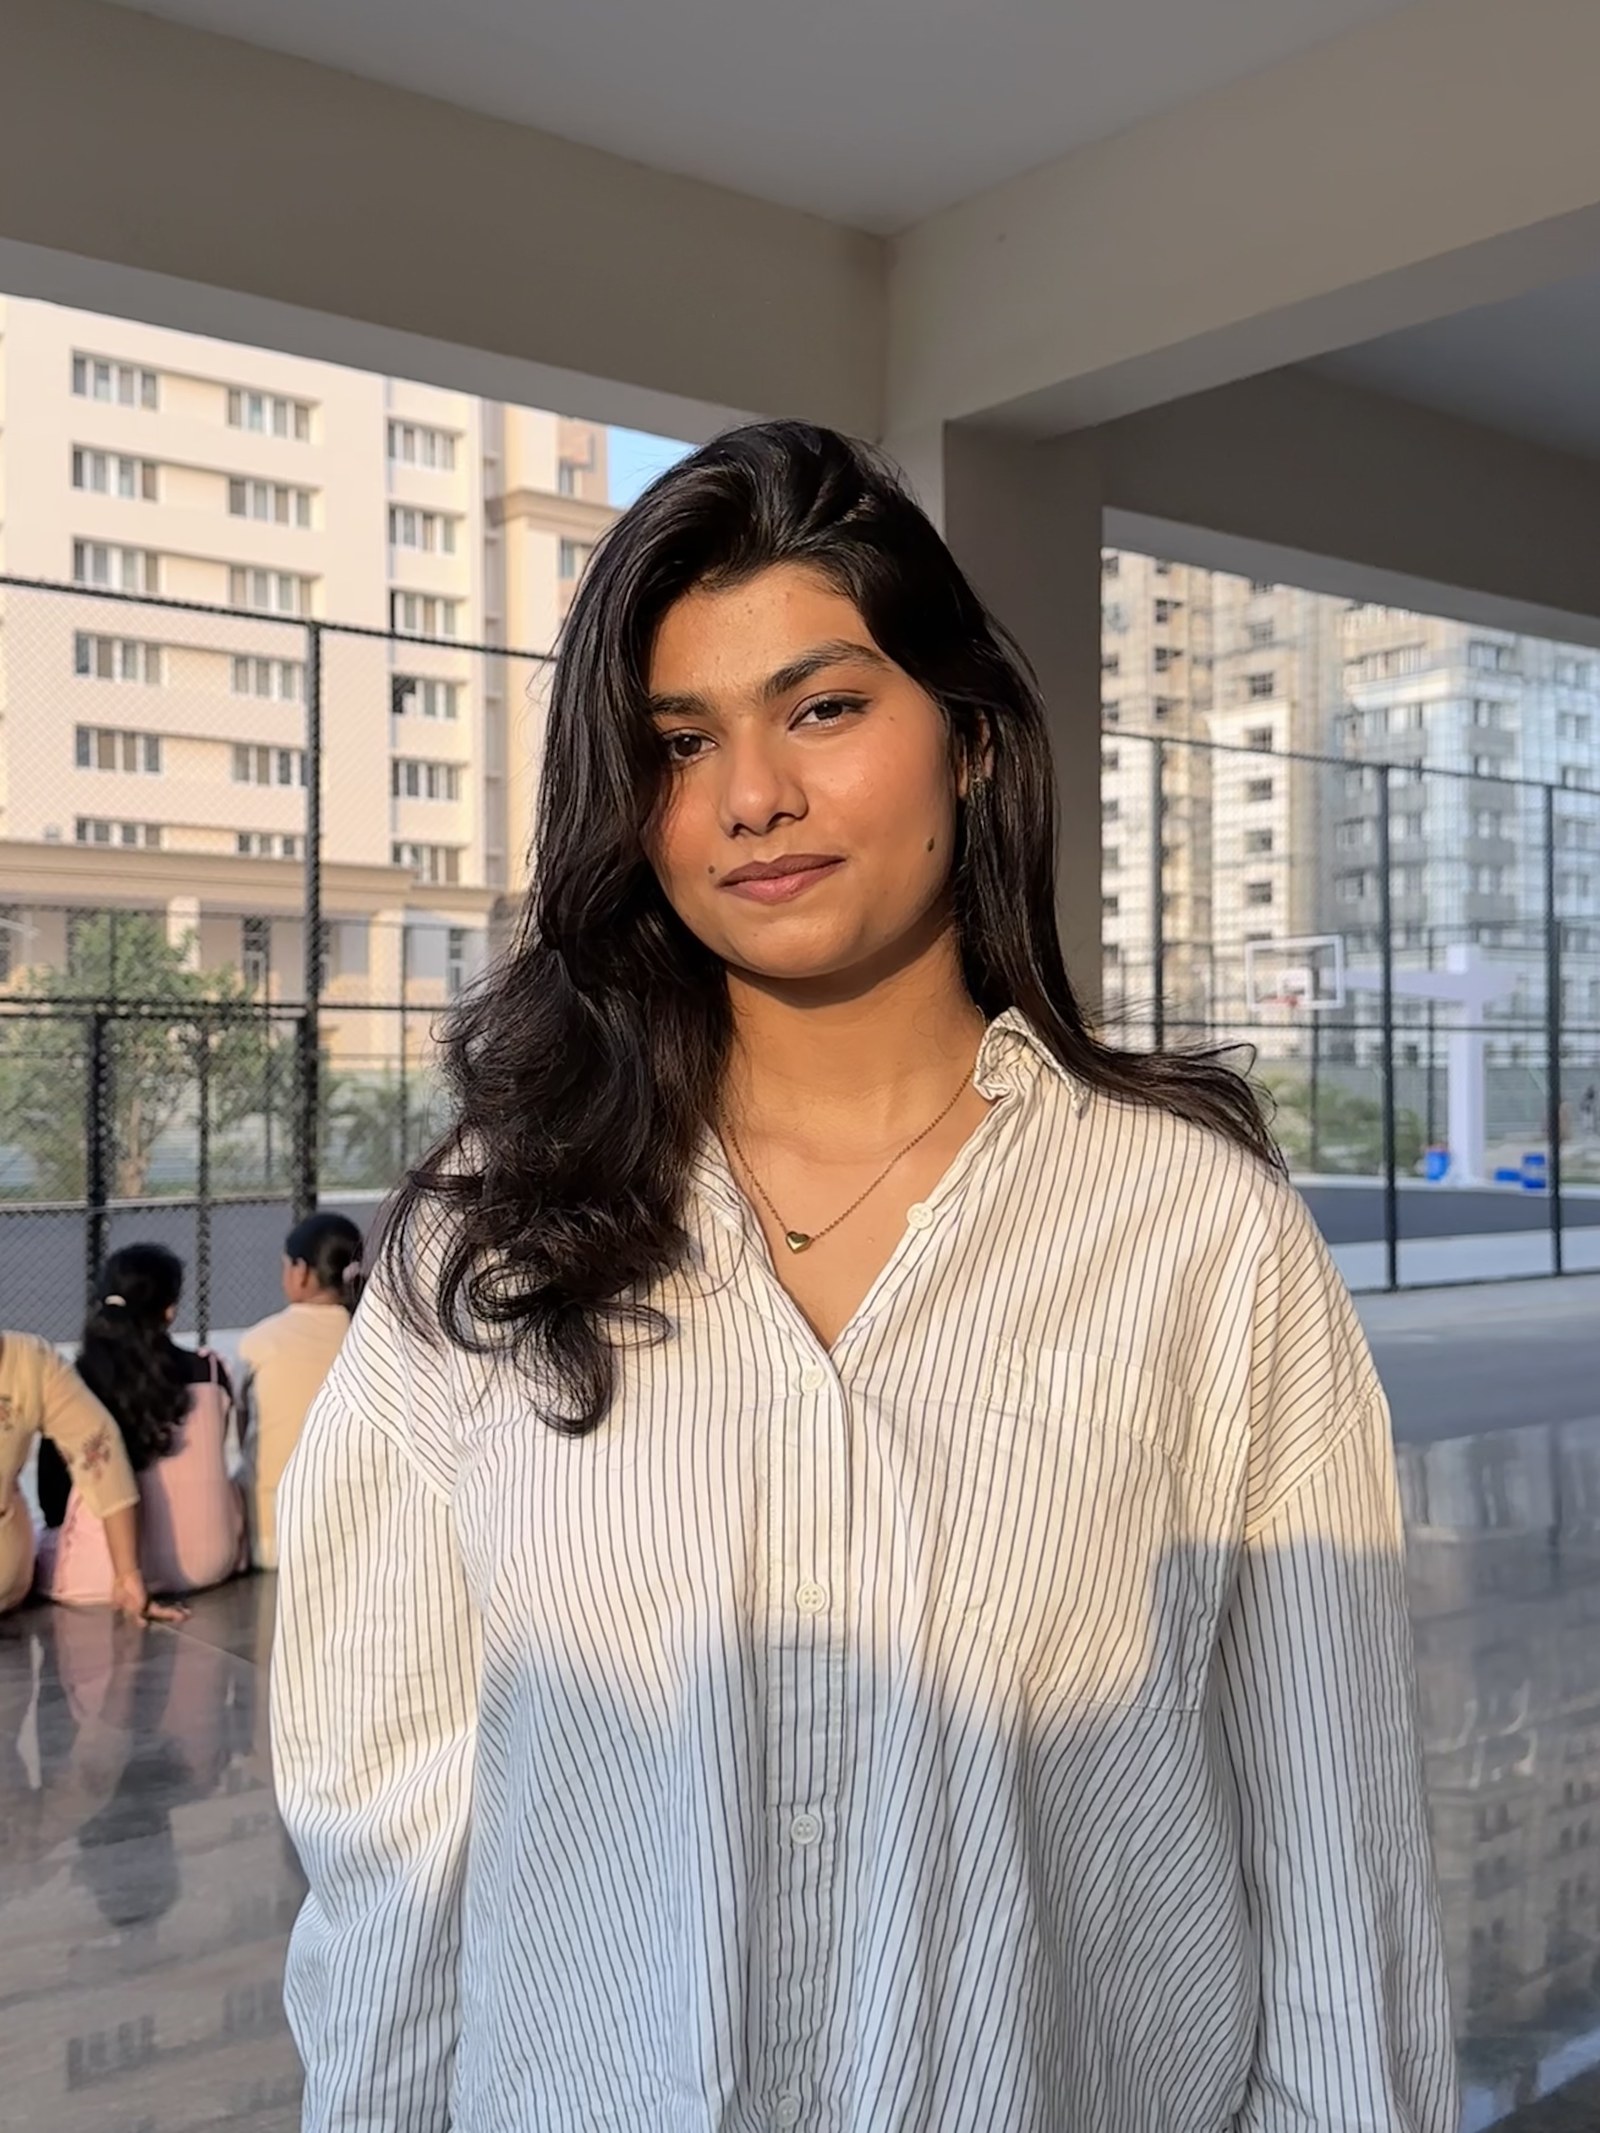
Who I am.
at VIT-AP
I work with Python, Java, C++, JavaScript, and SQL to build full-stack applications, backend systems, and AI-powered tools — from REST APIs and databases to model training and research pipelines.
My strengths span software engineering and applied AI — MERN stack development, computer vision, NLP research, and civic-tech platforms. I enjoy problems that need both solid engineering and thoughtful design.
“I don’t just study computer science — I ship software. Every project is built to work in the real world.”
Actively seeking software engineering internships and full-time roles across backend, full-stack, and AI/ML teams.
My stack.
Selected projects.
Work & research.
- 98.03% test accuracy · AUC 0.9994 on a 305-image held-out set
- Focal Loss, MixUp & CosineAnnealingWarmRestarts to handle class imbalance
- Grad-CAM++ heatmaps · zero false positives · 2.84% false-negative rate · Cohen’s κ 0.97 · F2 0.99
- Type-1 Mamdani fuzzy inference fused with part-based ResNet-50 features
- GMM-calibrated membership functions · SMOTE balancing · Youden-J / Max-F1 thresholds
- PETS 2009: 99.25% accuracy · 99.27% ROC-AUC · 98.75% mAP · 100% Rank-1
- Fine-tuned DistilRoBERTa & DistilBERT on Early Modern English corpus
- Six-class emotion classification (88.1% accuracy) & sentiment analysis (74.3% accuracy)
- Sentiment arc mapping across all acts and scenes with visualisations
- 1st Runner-Up, Smart India Hackathon 2025 finals · 2L+ national submissions
- AI-powered autofill · ~85–90%+ NLP/ML issue-categorization accuracy
- 1,000+ complaints tracked across 50+ locations · ~60–70% less reporting effort
- 94% identification accuracy on CCTV footage
- 70% reduction in manual search effort
Full overview.
- DBMS · Theory of Computation · DSA · DAA · Software Engineering · OS · Networks
- OOP · AI · Machine Learning · Python · Java
- 1st Runner-Up, SIH 2025 · ~85–90%+ NLP categorization accuracy · 1,000+ complaints tracked
- 94% accuracy · 70% manual effort reduction
- 88.1% emotion classification · 74.3% sentiment accuracy · Scientific Reports (under review)
- 98.03% accuracy · AUC 0.9994 · zero false positives · explainable heatmaps
- PETS 2009: 99.25% accuracy · 98.75% mAP · 100% Rank-1
- 1st Runner-Up — Smart India Hackathon 2025 (2L+ submissions)
- Top 10 — Google Cloud Sprint Hackathon
- 1st Runner-Up — Vikas Summit Ideathon
- AWS Academy — Cloud Architecting (Nov 2025)
- Oracle Cloud Infrastructure — Gen AI Professional (Aug 2025)
- IBM Cyber Security (Jun 2025)
- Crash Course on Python — Google (Mar 2022)
Download a copy of my full resume as a PDF, or explore my professional profiles online.
LinkedIn Profile GitHub Profile